---
title: VibeVoice
emoji: 🌍
colorFrom: purple
colorTo: yellow
sdk: docker
pinned: false
license: mit
short_description: VibeVoice-Realtime-0.5B - Real-time neural voice generation
---
## �️ VibeVoice: Open-Source Frontier Voice AI
[](https://microsoft.github.io/VibeVoice)
[](https://huggingface.co/collections/microsoft/vibevoice-68a2ef24a875c44be47b034f)
[](https://arxiv.org/pdf/2508.19205)
**Real-time neural voice synthesis system powered by Microsoft VibeVoice-Realtime-0.5B.**
*This Space demonstrates how to run the model using Docker on Hugging Face Spaces.*
## 🚀 Space Features
- ⚡ **Real-time voice generation** (~300ms latency)
- 🧠 **Lightweight 0.5B parameter model**
- 🐳 **Docker-based deployment** (downloaded at runtime)
- 🌐 **Runs on CPU** (Zero GPU supported)
---
## 📦 Model Details
- **Model:** [`microsoft/VibeVoice-Realtime-0.5B`](https://huggingface.co/microsoft/VibeVoice-Realtime-0.5B)
- **Type:** Text-to-Speech / Voice Generation
- **Inference:** Real-time Streaming
- **Source:** Microsoft Research
---
## 🏗️ Technical Overview (From Original Repo)
📰 News

 2025-12-03: 📣 We open-sourced VibeVoice‑Realtime‑0.5B.
To mitigate deepfake risks and ensure low latency for the first speech chunk, voice prompts are provided in an embedded format. For users requiring voice customization, please reach out to our team.
### Overview
VibeVoice is a novel framework designed for generating **expressive**, **long-form**, **multi-speaker** conversational audio.
It addresses significant challenges in traditional Text-to-Speech (TTS) systems, particularly in scalability, speaker consistency, and natural turn-taking.
**[Realtime streaming TTS model](docs/vibevoice-realtime-0.5b.md)**: Produces initial audible speech in ~**300 ms** and supports **streaming text input** for single-speaker **real-time** speech generation.


### 🎵 Demo Examples
**English**
https://github.com/user-attachments/assets/0967027c-141e-4909-bec8-091558b1b784
**Cross-Lingual**
https://github.com/user-attachments/assets/838d8ad9-a201-4dde-bb45-8cd3f59ce722
For more examples, see the [Project Page](https://microsoft.github.io/VibeVoice).
## Risks and Limitations
While efforts have been made to optimize it through various techniques, it may still produce outputs that are unexpected, biased, or inaccurate.
**Potential for Deepfakes and Disinformation:** High-quality synthetic speech can be misused. Users must ensure transcripts are reliable and avoid using generated content in misleading ways.
**Non-Speech Audio:** The model focuses solely on speech synthesis and does not handle background noise, music, or other sound effects.
We do not recommend using VibeVoice in commercial or real-world applications without further testing and development. This model is intended for research and development purposes only. Please use responsibly.
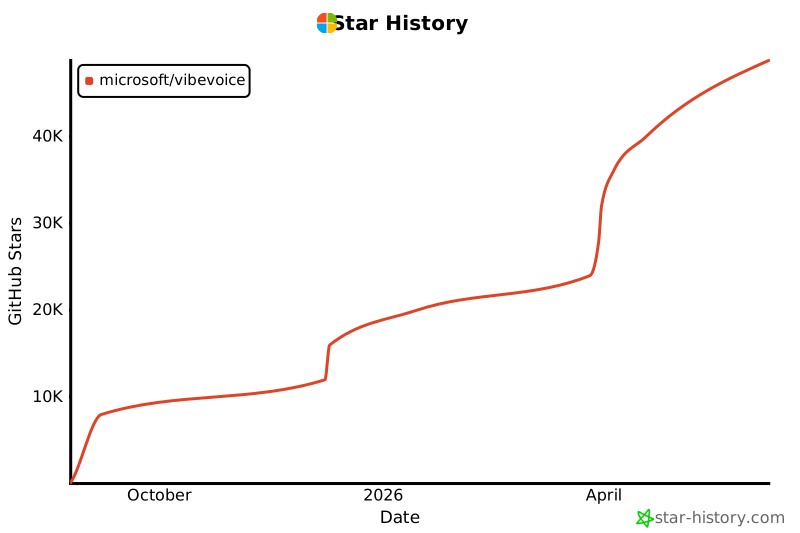
## Star History